The short version
- Alibaba Cloud Previews the Four-Tier Qwen4 Family at Apsara Amsterdam (Unveiled At: Alibaba Cloud Apsara Conference in Amsterdam; Model Lineup: Qwen4-Max, Qwen4-Plus, Qwen4-Flash, and Qwen4-27B).
- How Qwen4-Max, Plus, and Flash Split Heavy Reasoning and Low-Latency Workloads (Tier Positioning: Max/Plus for frontier API, Flash for low latency, 27B for local workstations).
- Why the 27B Size Class Hits the Sweet Spot for Local Apple Silicon and Single-GPU Runs (Open-Weight Hub: Official Qwen organization on Hugging Face).
At a glance
| Unveiled At | Alibaba Cloud Apsara Conference in Amsterdam |
|---|---|
| Model Lineup | Qwen4-Max, Qwen4-Plus, Qwen4-Flash, and Qwen4-27B |
| Tier Positioning | Max/Plus for frontier API, Flash for low latency, 27B for local workstations |
| Open-Weight Hub | Official Qwen organization on Hugging Face |
| Category | AI & Models |
| Creator / publisher | lewkao |
| Official link | huggingface.co ↗ |
| Heat | 🔥 21.5K Heat |
| Announced | |
| Data updated |
Alibaba Cloud Previews the Four-Tier Qwen4 Family at Apsara Amsterdam
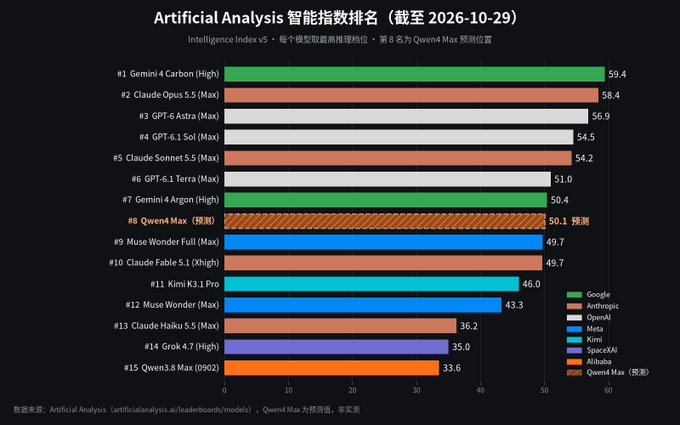
At the Apsara Conference in Amsterdam, Alibaba Cloud unveiled its upcoming Qwen4 model lineup, previewing four core tiers: Qwen4-Max, Qwen4-Plus, Qwen4-Flash, and a dense 27B model.
How Qwen4-Max, Plus, and Flash Split Heavy Reasoning and Low-Latency Workloads
The lineup spans frontier API flagships (Max and Plus), ultra-low-latency streaming (Flash), and a local-friendly 27B open-weight size class aimed at single-workstation and consumer Apple Silicon deployment.
Why the 27B Size Class Hits the Sweet Spot for Local Apple Silicon and Single-GPU Runs
Developers following the Qwen open-weight ecosystem can watch the official Qwen organization on Hugging Face for weight drops and quantized GGUF/MLX builds of the 27B tier.
FAQ
What are the key architectural specs and performance highlights of Alibaba Qwen4 Series Preview?
Unveiled At: Alibaba Cloud Apsara Conference in Amsterdam; Model Lineup: Qwen4-Max, Qwen4-Plus, Qwen4-Flash, and Qwen4-27B; Tier Positioning: Max/Plus for frontier API, Flash for low latency, 27B for local workstations. The lineup spans frontier API flagships (Max and Plus), ultra-low-latency streaming (Flash), and a local-friendly 27B open-weight size class aimed at single-workstation and consumer Apple Silicon deployment.
Where can developers and creators access and test Alibaba Qwen4 Series Preview?
Open-Weight Hub: Official Qwen organization on Hugging Face. Developers following the Qwen open-weight ecosystem can watch the official Qwen organization on Hugging Face for weight drops and quantized GGUF/MLX builds of the 27B tier.




