The short version
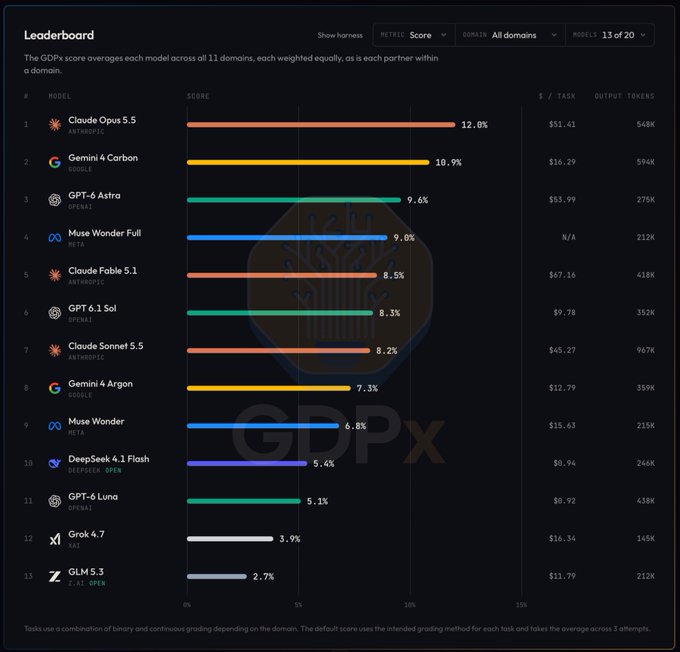
- Even the Best Model Scores 12%: SemiAnalysis Releases the 'GDPx' Frontier Agent Benchmark (Published By: SemiAnalysis (Semiconductor & AI research firm); Benchmark Scope: 206 end-to-end real-world tasks across 11 high-value economic domains).
- 206 Tasks Across 11 Economic Domains: Grading Real Deliverables Instead of Multiple-Choice Exams (Current Top Score: Even the strongest frontier model currently scores just 12%).
- Using GDPx Domain Breakdowns to Decide Where Human-in-the-Loop Reviews Remain Mandatory (Evaluation Style: Grades multi-step deliverables like financial models and chip verification scripts).
At a glance
| Published By | SemiAnalysis (Semiconductor & AI research firm) |
|---|---|
| Benchmark Scope | 206 end-to-end real-world tasks across 11 high-value economic domains |
| Current Top Score | Even the strongest frontier model currently scores just 12% |
| Evaluation Style | Grades multi-step deliverables like financial models and chip verification scripts |
| Category | AI & Models |
| Creator / publisher | SemiAnalysis |
| Official link | semianalysis.com ↗ |
| Heat | 🔥 672.5K Heat |
| Announced | |
| Data updated |
Even the Best Model Scores 12%: SemiAnalysis Releases the 'GDPx' Frontier Agent Benchmark
SemiAnalysis released GDPx, a rigorous frontier benchmark evaluating autonomous AI agents across 206 real-world tasks spanning 11 high-value economic domains—where even the strongest current model scores just 12%.
206 Tasks Across 11 Economic Domains: Grading Real Deliverables Instead of Multiple-Choice Exams
Unlike saturated multiple-choice exams, GDPx grades end-to-end multi-step deliverables such as financial modeling, chip verification scripts, and legal contract redlines.
Using GDPx Domain Breakdowns to Decide Where Human-in-the-Loop Reviews Remain Mandatory
Use GDPx domain breakdowns to identify where human-in-the-loop checkpoints remain mandatory when deploying enterprise workflows.
FAQ
What real-world tasks does GDPx Benchmark evaluate and how did frontier models score?
Published By: SemiAnalysis (Semiconductor & AI research firm); Benchmark Scope: 206 end-to-end real-world tasks across 11 high-value economic domains; Current Top Score: Even the strongest frontier model currently scores just 12%. Unlike saturated multiple-choice exams, GDPx grades end-to-end multi-step deliverables such as financial modeling, chip verification scripts, and legal contract redlines.
What does this benchmark mean for teams deploying AI agents in production?
Evaluation Style: Grades multi-step deliverables like financial models and chip verification scripts. Use GDPx domain breakdowns to identify where human-in-the-loop checkpoints remain mandatory when deploying enterprise workflows.




