The short version
- Backed by a $27.5M Series A, Phonic Launches 'Phonic-1' for Agentic Voice Tool Use (Company & Funding: Phonic (10-person team; $27.5M Series A led by First Round Capital); Architecture: Phonic-1 native end-to-end speech-to-speech foundation model).
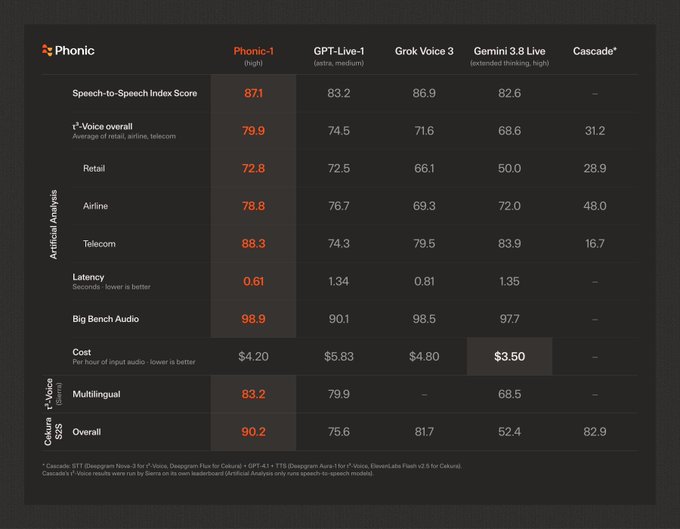
- Ditching the STT-LLM-TTS Cascade: How 610ms Native Audio Eliminates Awkward Pauses (End-to-End Latency: ~610ms response time with natural barge-in and turn-taking).
- Structuring Lean Tool Schemas and Conversational Fillers for Live Database Lookups (Core Specialty: Mid-conversation agentic tool calling without awkward pauses).
At a glance
| Company & Funding | Phonic (10-person team; $27.5M Series A led by First Round Capital) |
|---|---|
| Architecture | Phonic-1 native end-to-end speech-to-speech foundation model |
| End-to-End Latency | ~610ms response time with natural barge-in and turn-taking |
| Core Specialty | Mid-conversation agentic tool calling without awkward pauses |
| Category | AI & Models |
| Creator / publisher | Moin Nadeem |
| Official link | phonic.co ↗ |
| Heat | 🔥 1M Heat |
| Announced | |
| Data updated |
Backed by a $27.5M Series A, Phonic Launches 'Phonic-1' for Agentic Voice Tool Use
Announced alongside a $27.5M Series A led by First Round Capital, Phonic-1 is an end-to-end speech-to-speech model engineered specifically for real-time agentic tool calling and natural turn-taking.
Ditching the STT-LLM-TTS Cascade: How 610ms Native Audio Eliminates Awkward Pauses
Unlike traditional ASR-plus-LLM-plus-TTS cascades, Phonic-1 processes acoustic nuances directly with ~610ms latency and triggers external APIs mid-conversation without awkward pauses.
Structuring Lean Tool Schemas and Conversational Fillers for Live Database Lookups
Define concise JSON schemas for tool calls and enable streaming filler acknowledgments so database lookups feel seamless to the caller.
FAQ
What are the key architectural specs and performance highlights of Phonic-1?
Company & Funding: Phonic (10-person team; $27.5M Series A led by First Round Capital); Architecture: Phonic-1 native end-to-end speech-to-speech foundation model; End-to-End Latency: ~610ms response time with natural barge-in and turn-taking. Unlike traditional ASR-plus-LLM-plus-TTS cascades, Phonic-1 processes acoustic nuances directly with ~610ms latency and triggers external APIs mid-conversation without awkward pauses.
Where can developers and creators access and test Phonic-1?
Core Specialty: Mid-conversation agentic tool calling without awkward pauses. Define concise JSON schemas for tool calls and enable streaming filler acknowledgments so database lookups feel seamless to the caller.




