The short version
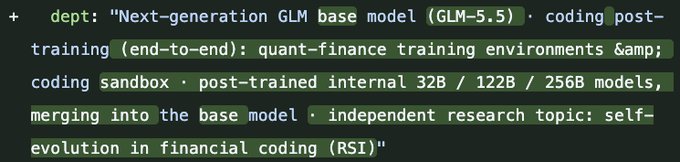
- Benchmark Tracker Leak: Zhipu AI's GLM-5.5 Enters Late Post-Training in 32B, 122B, and 256B Sizes (Developer: Zhipu AI; Reported Size Tiers: 32B, 122B, and 256B parameter variants).
- Why the 32B Tier Excites Local LLM Users: Fitting Inside 16GB Laptops at 4-Bit Quantization (Current Phase: Late-stage post-training and checkpoint merging).
- How the 122B and 256B Tiers Target Agentic Coding and What Remains Unconfirmed (Local LLM Appeal: 32B tier fits in ~16GB unified memory/VRAM at 4-bit quantization).
At a glance
| Developer | Zhipu AI |
|---|---|
| Reported Size Tiers | 32B, 122B, and 256B parameter variants |
| Current Phase | Late-stage post-training and checkpoint merging |
| Local LLM Appeal | 32B tier fits in ~16GB unified memory/VRAM at 4-bit quantization |
| Category | AI & Models |
| Creator / publisher | Lumina |
| Heat | 🔥 142.3K Heat |
| Announced | |
| Data updated |
Benchmark Tracker Leak: Zhipu AI's GLM-5.5 Enters Late Post-Training in 32B, 122B, and 256B Sizes
Benchmark tracker Lumina reported that Zhipu AI's next-generation GLM-5.5 series is now deep into post-training, built around internal 32B, 122B, and 256B parameter tiers.
Why the 32B Tier Excites Local LLM Users: Fitting Inside 16GB Laptops at 4-Bit Quantization
The 32B tier is drawing particular interest from local-inference users because a 4-bit quantization fits comfortably inside ~16GB of unified memory on consumer laptops.
How the 122B and 256B Tiers Target Agentic Coding and What Remains Unconfirmed
Treat third-party parameter and merge specs as unconfirmed until Zhipu AI publishes official model cards and weights.
FAQ
What specs and pricing details surfaced in the GLM-5.5 Post-Training Leak leak?
Developer: Zhipu AI; Reported Size Tiers: 32B, 122B, and 256B parameter variants; Current Phase: Late-stage post-training and checkpoint merging. The 32B tier is drawing particular interest from local-inference users because a 4-bit quantization fits comfortably inside ~16GB of unified memory on consumer laptops.
How should developers treat these unconfirmed details before an official release?
Local LLM Appeal: 32B tier fits in ~16GB unified memory/VRAM at 4-bit quantization. Treat third-party parameter and merge specs as unconfirmed until Zhipu AI publishes official model cards and weights.




