The short version
- Clover-35B-A3B-Preview from DiffuSpace Labs is presented as the first open-weight production diffusion language model (dLLM) at the 35B parameter scale.
- Adapted from Qwen3.6-35B-A3B, it combines 35B total parameters with ~3B active parameters, a 128K context window, and an Apache 2.0 license.
- Instead of token-by-token autoregression, it uses parallel generation, bidirectional modeling, and iterative refinement to hit 680 tokens per second on a single GPU at BF16.
- Weights are available today on Hugging Face, ModelScope, and the official DiffuSpace site.
At a glance
| Model name | Clover-35B-A3B-Preview |
|---|---|
| Parameters | 35B total / ~3B active (derived from Qwen3.6-35B-A3B) |
| Throughput | Up to 680 tokens per second on a single GPU card at BF16 |
| Context & license | 128K context window, Apache 2.0 open-weight license |
| Distribution | Hugging Face (DiffuSpace), ModelScope, and diffuspace.ai |
| Category | AI & Models |
| Creator / publisher | DiffuSpace |
| Official link | huggingface.co ↗ |
| Heat | 🔥 179.6K Heat |
| Announced | |
| Data updated |
Moving past left-to-right autoregression with parallel generation
Nearly every mainstream large language model decodes text autoregressively, predicting one token after another in a strict left-to-right sequence. That serial bottleneck caps single-stream generation speed no matter how much compute sits idle on the accelerator. DiffuSpace—a 13-member research team whose Hugging Face roster includes Oran Feng, Weitong Lian, Shengliang Deng, Zirui Wu, Guicheng Qi, Demi Zhu, Shansan Gong, and Jiacheng Ye—built Clover-35B-A3B-Preview to push foundation models beyond autoregression.
As a diffusion language model (dLLM), Clover-35B-A3B-Preview generates and refines multiple tokens in parallel using bidirectional context and iterative denoising steps. Because it does not wait for each preceding token to finish before computing the next, it achieves up to 680 tokens per second on a single GPU card running at standard BF16 precision.
Sparse 35B-A3B architecture built on Qwen3.6-35B-A3B
To pair high throughput with strong reasoning and language quality, DiffuSpace adapted Clover-35B-A3B-Preview from the sparse Qwen3.6-35B-A3B backbone. While the checkpoint holds 35 billion total parameters, only about 3 billion parameters are activated per step, keeping memory bandwidth demands low enough for single-card BF16 deployment.
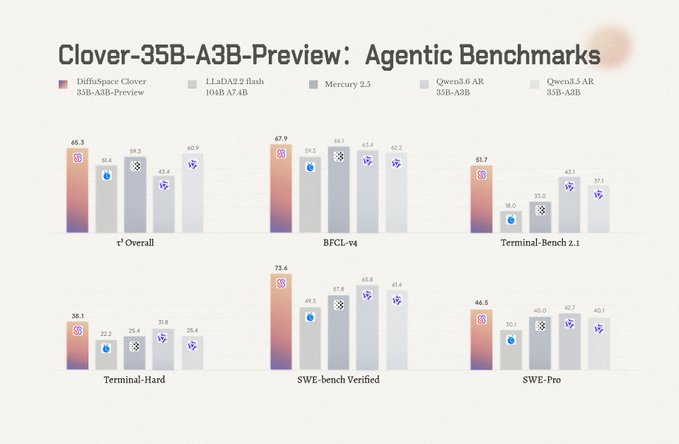
The model supports a 128K context window and is released under the permissive Apache 2.0 license. According to DiffuSpace Labs, Clover-35B-A3B-Preview delivers competitive results not only against earlier diffusion language models, but also against matched autoregressive models.
- Parallel generation
Produces token blocks simultaneously rather than decoding one token per forward pass, unlocking 680 tps at BF16 on one card.
- Bidirectional modeling
Attends across the full span in both directions during refinement, aiding global coherence and controllable text infilling.
- Iterative refinement
Progressively sharpens draft token predictions across diffusion steps while keeping active compute around 3B parameters.
Where to download the weights and test the model
DiffuSpace has published the open weights for Clover-35B-A3B-Preview across both international and Chinese model hubs. Developers can pull the checkpoint directly from the DiffuSpace organization on Hugging Face or from ModelScope, as well as read the project overview and research notes on diffuspace.ai.
Because the weights carry an Apache 2.0 license and run at BF16 on a single GPU without requiring exotic quantization just to reach high token speeds, teams building low-latency coding assistants, real-time document generators, or bidirectional editing tools can benchmark a production-scale diffusion LLM on their own hardware.
How to try it
Visit the DiffuSpace Hugging Face hub
Use the action link above to open the DiffuSpace organization page on Hugging Face (or ModelScope) and locate the Clover-35B-A3B-Preview repository.
Provision a single BF16-capable GPU
Set up a single GPU environment with enough VRAM for the 35B total (3B active) BF16 weights and 128K context support.
Run parallel diffusion inference
Execute the diffusion generation pipeline to benchmark token throughput (rated up to 680 tps at BF16) against standard autoregressive baselines.
Explore bidirectional and refinement tasks
Test structured generation, code infilling, and long-context workloads under the Apache 2.0 license.
FAQ
What makes Clover-35B-A3B-Preview different from standard LLMs?
It is a diffusion language model (dLLM) that uses parallel generation, bidirectional modeling, and iterative refinement rather than left-to-right token-by-token autoregression.
How fast does Clover-35B-A3B-Preview run on a single GPU?
DiffuSpace reports that the model reaches 680 tokens per second (tps) on a single GPU card at BF16 precision.
What base model and license does Clover-35B-A3B-Preview use?
It is adapted from Qwen3.6-35B-A3B (35B total parameters, ~3B active, 128K context window) and released under the Apache 2.0 open-weight license.
Where can I download Clover-35B-A3B-Preview?
The open weights are hosted on Hugging Face under the DiffuSpace organization, on ModelScope, and via diffuspace.ai.




